Search This Blog

Showing posts with label secondary structure. Show all posts

Wednesday, August 18, 2010

Demonstration of GSoC Project

The features that developed for the GSoC project will be available in the next Jalview release. You can also contact me and I can send you a jar file with the new features, or download the code from the Google code hosting page for Jalview and see my post on how to set up Eclipse with Jalview. The code submitted to Google is the same as rev 32 on the Google code host site.

Addendum: Jim posted a comment with a link to the webstart version.


  1. You can fetch sequences from RFAM via the sequence fetcher. Go to "File > Fetch Sequence(s)..." and a dialog box will appear.


  2. From the database drop down menu select RFAM (Full) for the "Full" alignment from RFAM or RFAM (Seed) for the "Seed" alignment. Seed alignments are the original alignments constructed to create a covariance model for searching databases. Full alignment are the result of a search using the covariance model against the sequence database. For this demonstration, I used RFAM (Seed), but selecting the RFAM (Full) will be very similar.

  3. Click the "Example" button to load an alignment name. Click the "OK" button to fetch the alignment.


  4. A new dialog box will appear with the alignment. The RFAM sequence fetcher retrieves files in Stockholm format, so Jalview can interpret the secondary structure information in the file. The secondary structure information in the file is displayed in WUSS notation and helices that are determined from this information are displayed as blue arrows in the Annotation panel.


  5. You can color the helices with the "By RNA helices" color option. Go to "Colour > By RNA helices."


  6. The helices should now be colored.


  7. To view the consensus logo in the Annotation panel, go to "View > Autocalculated Annotation > Show Consensus logo". The coloring of the logo will change based on which color scheme is selected.


  8. Close up of Consensus logo when "By RNA helices" or "Purine/Pyrimidine coloring is selected.


  9. To change the color scheme to "Purine/Pyrimidine" go to "Colour > Purine/Pyrimidine"


Thursday, June 3, 2010

How RALEE parses the secondary structure line

I've figured out how RALEE interprets the secondary structure line and figures out helices…I really don't like Lisp, haha. The GNU Emacs Lisp Reference Manual isn't too bad: http://www.gnu.org/software/emacs/manual/html_mono/elisp.html

Basically, this is what happens, in two separate functions.

Parse the secondary structure line from the Stockholm file (ralee-get-base-pairs)

Description: Keep a list of the positions of the open brackets and a list whose elements are paired positions. When you reach a close bracket, pair it with the last open bracket and store this pair in the "pairs" list.

  • Split the line into a "position" list (each character of the line is an element of the list)

  • Keep a "stack" list and a "pairs" list

  • Go through each element of the "position" list
    *if the base is an open bracket type, add the current position as the first element of the "stack" list

    *if the base is a close bracket type, create a 2 element list that consists of the first element of "stack" list and the current position. Add this list as the first element of the "pairs" list and remove the first element from the stack list.

Numbers indicate the order in which the pairs are added to the "pairs" list

<<..<<..>>..<<..>>>>
65..21..12..43..3456

Create a Hash of positions and which helix they belong to (ralee-helix-map)
Description: This function takes the pairs list generated by the above function as its input. It goes through the pairs and figures out how many helices there are and creates a hash where the keys are positions and the values are which helix they belong to.

Variables:
helix = the current helix, an int
helices = hash of the positions and which helix they belong to
lastclose = position of the last close bracket reviewed
lastopen = position of the last open bracket reviewed
open = position of current open bracket
close = position of current close bracket
pair = current pair (consists of open and close)
pairs = list of base pairs (input, elements are 2 element lists)
i = current pair (in pairs list)

  • Go through each item in pairs list

    *for the current pair, open is the first element and close is the second element
    *Check for an inner helix:
     catch things like
    ; <<..>>..<<..>>
    ; *
    if the lastclose comes before open, increment the current helix
    *Check for bulges:
     catch things like
    ; <<..<<..>>..<<..>>>>
    ; *

    <<..<<..>>..<<..>>>>
    cc..aa..aa..bb..bbcc

    compare current pair to all other pairs (this works because of the way that the pairs are stored)
    **if open of a pair comes before lastopen and also after current open
    **then find which helix the open belongs to. If it belongs to the current helix, do nothing. Otherwise increment the number of helices.

  • add the current open and close to the helices hash with the helix as the value

  • set lastopen and lastclose to open and close

Wednesday, June 2, 2010

Parsing WUSS notation of RNA secondary structure annotation

A key part of this project is to parse the secondary structure line of Stockholm files so that it can be interpreted for coloring schemes. I have been adding mini-goals as appropriate. I will probably also need to add code to check that the sequence length and secondary structure length are the same, as well as the same number of open and closed parentheses.

WUSS notation is used in RNA stockholm files to indicate secondary structure. WUSS notation can support more characters than I thought, but Rfam uses the simplified version that the covariance modeling program Infernal uses. The description of Rfam on the Janelia Farm page is


Rfam is a collection of multiple sequence alignments and covariance models covering many common non-coding RNA families. The main use of Rfam is as a source of RNA multiple alignments with consensus secondary structure annotation in a consistent format. In conjunction with the Infernal software package, Rfam covariance models (CMs) can be used to search genomes or other DNA sequence databases for homologs to known structural RNA families.


WUSS notation uses <>, (), [], and {} to indicate base pairs and ':', ',', '_', '.', and '~' as single stranded columns. Each type of symbols has subtle meaning, but for Infernal the structure annotation line only needs to indicate which columns are base paired to each other. Thus, full WUSS notation is not necessary and a simple minimal annotation uses <> to indicate base pairs and '.' for single stranded positions of the alignment.

In more detail taken from the Infernal user guide:

Base pairs: the different symbols indicate different depth
*<> for simple terminal stems
*() for "internal" helices enclosing a multifunction of all terminal stems
*[] for internal helices enclosing a multifunction that includes at least one annotated () stem already
*{} for all internal helices enclosing deeper multifurcations

Hairpin loops
*indicated by underscores '_'
*Simple stem loops example: <<<____>>>

Bulge, interior loops
*indicated by dashes '-'

Multifurcation loops
*indicated by commas ','
*example: <<<___>>>,,<<<__>>>

External residues completely outside structure
*indicated by colons ':'

Insertions
* . to a known structure
* ~ used to indicate that a local structural alignment left regions of target and query unaligned.

Pseudoknots
* pairs of upper case/lower case letters
* example: <<<<_AAAA____>>>>aaaa


Things that I am thinking about:

-I need to interpret WUSS notation in a general way. It shouldn't be too difficult, but it is necessary since the same structure can be written in multiple ways. An example from the Infernal user guide is : <<<<....>>>> and ((((____)))) and <(<(._._)>)> all indicate a four base stem with a four base loop

-How should I store the secondary structure line so that it will be easily interpreted to implement coloring schemes?

Potentially I can store pairs of positions like how the disulfide bond positions are stored as annotations (Jim pointed this one out). I also need to keep in mind that bulges might exist, so I can't just interpret a run of the same type of bracket as part of the same stem. VARNA interprets bulges just fine, so I don't have to worry about that. An example of a complicated structure with a bulge:

<<<<……<<<< <<<<…..>>>>..>>>>……<<<<…>>>>….>>>>

-How can I make sure that there are 4 stems instead of 3? I can't simply scan through from left to right or eat away at both ends at the same time. It looks like the RALEE mode for Emacs handles bulges just fine based on this example in the readme
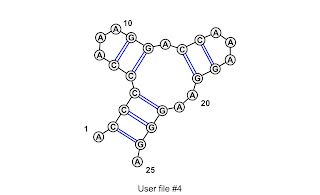


0123456789012345678901234
.<<<<<...>>.<<...>>..>>>.


Column 1 pairs with 23
2 with 22
3 with 21
4 with 10
5 with 9
12 with 18
13 with 17


The image is from VARNA. Note the numbering in the image starts at 1 instead of 0.

RALEE is written in Emacs Lisp, so I need to look up some basics in Lisp before I can feel confident that I'm interpreting the code correctly! I think that this code will cut down on my thinking time, however.

To do
-check that secondary structure line and sequence are the same length. Does Jalview already do this?
-change all bracket types to () for VARNA (I just noticed that VARNA only likes (), not <> for base pairing! )
-convert all WUSS symbols to something simple, like how Jalview already does for protein secondary structure (simple helices and sheets)
-Need to figure out how to detect pseudoknots
-Add support for error checking when a user adds a base pair annotation. Make sure same number of column groups are selected
-How will colors cycle for different numbers of stems?

Thursday, May 20, 2010

RNA Secondary Structure Viewers

One of the goals of this project is to embed a secondary structure viewer into Jalview for RNA. At today's meeting with Jim, it looks like there might be some interactive editing features that we'd like to implement into VARNA, if we choose it. Adding interactive base connection making and breaking would be nice. I'm pretty sure that we will use VARNA. The advantages of VARNA are:

1. It is written in Java and under the GPL license. This means that it can be easily added to Jalview.

2. You can specify secondary structure with WUSS notation

3. It exports the image you make in a variety of formats

4. (My opinion) It has pretty output.

5. You can add annotations and change color of bases

6. Other features allow different visualization schemes, such as basepairing and modes such as "Feynman's diagram"

7. Can handle a variety of file formats (.ct, .dbn, etc)

One interesting thing about VARNA is that it can create multiple panels in the visualization window. This might be useful for comparing a multiple sequence alignment. On the other hand, another type of visualization might be useful, such as overlaying the structures and using color to indicate conservation.

After looking at various RNA structure viewers, it looks like it might be useful to add more valid file formats in Jalview, such as ConnecT (.ct), Base Pair Sequence (.bpseq), and Dot Bracket Notation (.dbf, .dbn).

Below is a list of some RNA secondary structure viewers that I've looked at.

VARNA: Visualization Applet for RNA
http://varna.lri.fr/index.html

RNA-DV
http://rna-dv.sourceforge.net/

jViz.RNA 2.0
http://jviz.cs.sfu.ca/index.html

XRNA
http://rna.ucsc.edu/rnacenter/xrna/xrna.html

RNA2D3D
http://www-lmmb.ncifcrf.gov/~bshapiro/structurelab/structureLab.html

SStructView
http://helix-web.stanford.edu/sstructview/home.html

RNAmovies
http://bibiserv.techfak.uni-bielefeld.de/rnamovies/

RnamlView
http://ndbserver.rutgers.edu/services/help/rnamlview-readme.html

List from: http://openwetware.org/wiki/Wikiomics:Alignment_visualization_and_plotting_RNA_structures